
You can turn off your Wi-Fi, unplug your ethernet cable, and still have a fluid conversation with an advanced artificial intelligence. Generative AI historically required a constant connection to giant cloud server farms to process your questions. But today, you can download a pre-trained file to your local computer and generate answers entirely offline. The software does not search the web to find what you are asking. Instead, it relies on a downloaded package of mathematical “weights” to guess the next most probable word in a sequence.
The secret lies in the difference between how an AI learns and how it speaks. A model requires the internet and massive computing power during its initial training phase. It reads billions of web pages to learn the patterns of human language. But once that training is done, developers compress those learned patterns into a standalone file. Generating text with that downloaded file is a separate, entirely offline process called inference. The computer uses pure probability, not active web searches, to write its responses.
Step-by-Step Instructions: The Mechanics of Offline Inference
To understand how a computer writes without the internet, we have to look at how it breaks down language into math. When you type a prompt into an offline AI, the software immediately translates your English words into numbers. Here is the exact sequence of events that happens inside your machine.
Step 1: Tokenization and Embeddings
The model cannot read letters. It breaks your prompt down into fragments called tokens. A short word might be one token, while a long word gets chopped into two or three pieces. The software then maps these tokens to mathematical vectors known as embeddings. Because the AI already learned the relationships between words during its cloud training, it knows that the math vector for “king” is closely related to “queen.” It processes your entire prompt to understand the semantic context.
Step 2: The Prefill Phase
Offline inference happens in two distinct stages. According to technical documentation from engineers at IBM, the first stage is the prefill phase. Your computer’s processor ingests your entire text prompt at once. This requires heavy computational power because the model is trying to establish the initial context for its reply before it generates a single letter.
Step 3: The Autoregressive Decode Phase
This is where the actual writing happens. The AI uses a Transformer architecture and an attention mechanism to look at your prompt and mathematically predict the statistically most probable next token. It picks the word, outputs it to your screen, and then feeds that new word back into its own equation. The process repeats in a loop. Documentation published on Microsoft Learn explains how generative AI models build output regressively to form coherent paragraphs without external web calls.
Step 4: KV Caching for Speed
Predicting words one by one takes a long time. If the model had to recalculate the math for the entire conversation every time it wanted to pick a new word, your computer would freeze. To fix this, local software uses Key-Value (KV) caching. As the AI generates a token, it saves the intermediate mathematical state of that word in your computer’s memory. The next time the loop runs, the model just pulls the saved math from the cache instead of starting over.
Hardware Requirements for Local AI
You cannot run a modern language model on just any old laptop. Because the software is constantly doing heavy matrix multiplication, the hardware inside your machine dictates how fast the AI can read and write.
- System Memory (RAM): Your computer needs enough RAM to hold the entire file of neural weights open at once. If you download an 8-gigabyte model, you need at least 8 gigabytes of free RAM just to load it, plus extra memory to run your operating system.
- Graphics Processing Units (GPUs): Standard central processing units (CPUs) calculate tasks one at a time. GPUs calculate thousands of math problems simultaneously. Running an offline AI on a GPU makes the decode phase drastically faster.
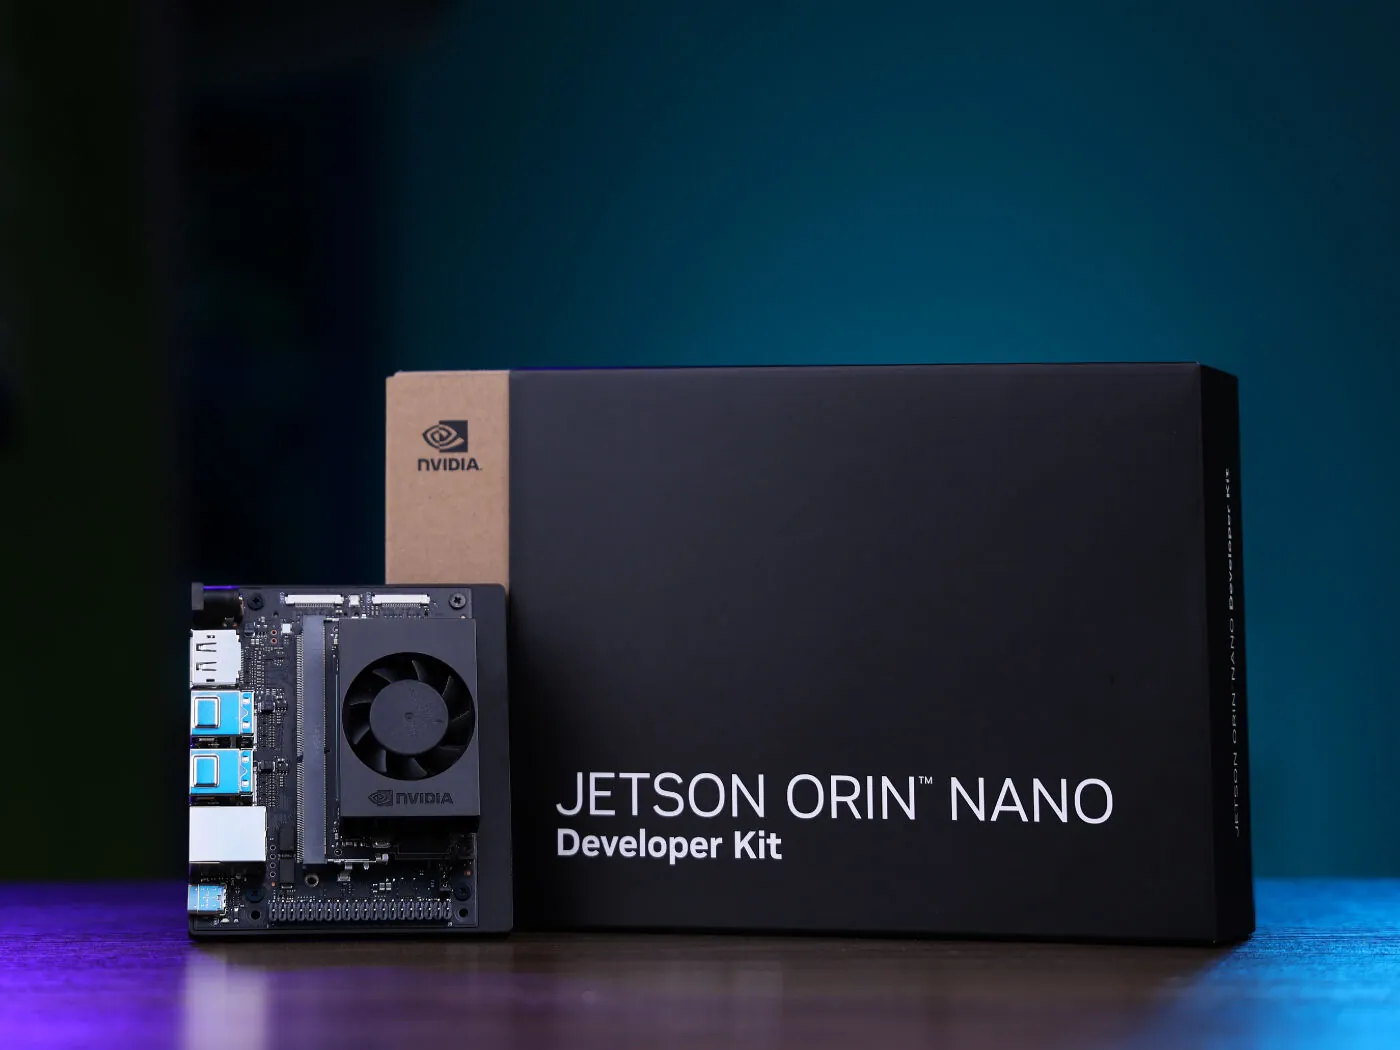
- Neural Processing Units (NPUs): Recent smartphones and PCs now include NPUs. These are specialized chips built specifically to handle AI math efficiently without draining your battery.
Developers use tools like Ollama, vLLM, and the Microsoft Foundry Local SDK to compress these models so they fit on consumer hardware. These runtimes squeeze the neural weights down into smaller file sizes. A guide on the Microsoft Tech Community Hub details the rise of Small Language Models, which run entirely on local NPUs and GPUs to give users absolute privacy and zero network latency.
Real-World Uses for Disconnected AI
Taking the AI off the cloud solves several practical problems for industries that cannot rely on a constant internet connection.
Automotive and Robotics Integration
Self-driving cars and autonomous robots need to process voice commands and visual data instantly. If a car drives through a long tunnel and loses its cell signal, its voice assistant still needs to work. Automotive manufacturers install embedded C++ frameworks directly into the vehicle’s computer. A 2026 NVIDIA Technical Blog post highlights how carmakers use embedded hardware to run vision and language logic locally, completely independent of cloud servers.
Defense and Secure Laboratories
High-security sectors deliberately isolate their computers from the internet to stop hackers. These isolated networks are known as air-gapped systems. A 2026 paper published on MIT DSpace outlines how military contractors and intelligence agencies deploy completely offline language models to summarize classified documents and prevent data leakage. Because the AI never pings an external server, the proprietary data never leaves the physical building.
Common Issues and Alternative Fixes
Running a language model offline comes with highly specific technical limitations. The most obvious problem is the “knowledge cutoff.”
Because the AI is totally disconnected from the web, it has no idea what happened in the world this morning. Its knowledge is permanently frozen at the exact moment its developers finished training it. If you ask an offline model for today’s weather or the score of a live sports game, it will fail. Worse, it might hallucinate. Since the model is just a math engine designed to guess the next word, a lack of factual data often causes it to string together highly plausible but completely fake sentences just to complete the sequence.
The Fix: Local Retrieval-Augmented Generation (RAG)
You can bypass the knowledge cutoff without turning your Wi-Fi back on. Developers use a method called offline Retrieval-Augmented Generation (RAG) to feed fresh facts to a frozen model. Instead of connecting the AI to the internet, you point the AI software to a local folder on your hard drive full of PDFs, spreadsheets, or text documents. When you ask a question, the software searches your local files first, extracts the relevant paragraphs, and temporarily pastes them into the AI’s prompt. The model reads your local documents and generates an accurate answer based strictly on your personal files.
Frequently Asked Questions
Can an AI chatbot work completely offline?
Yes. If you download a pre-trained language model and an inference engine like Ollama directly to your local device, the AI can read prompts and generate text entirely without an internet connection.
Does an offline LLM search its downloaded files to answer questions?
Not inherently. A standard offline language model generates answers based on complex mathematical probabilities derived from the weights it learned during its initial training. However, it can be paired with an offline Retrieval-Augmented Generation system. This specific setup explicitly tells the model to read and pull facts from local PDFs or text files stored directly on your hard drive.
What kind of computer do I need to run a large language model offline?
Offline inference relies heavily on system memory and processing speed. You generally need a machine with a minimum of 8GB to 16GB of RAM just to hold the model weights open. Having a dedicated Graphics Processing Unit or a modern Neural Processing Unit significantly speeds up the text generation process compared to relying entirely on a standard central processor.
Why do some offline language models hallucinate or generate false facts?
Because offline models do not have access to live web searches to verify facts, they rely entirely on the statistical likelihood of words following one another. If the model’s training data lacked sufficient information on a particular topic, its algorithm simply pieces together the most mathematically plausible words. This often results in the computer outputting confident but factually incorrect statements.